What One 4090 Does With a 7B Model, for One User
Measuring a 7B model on an RTX 4090 for one user: how fast it writes, why, and the same model at 4 bits.
In the first post I said I would start with a 7B model at 16-bit, measure it, then quantize the same model and measure it again. This post covers that, for one user.
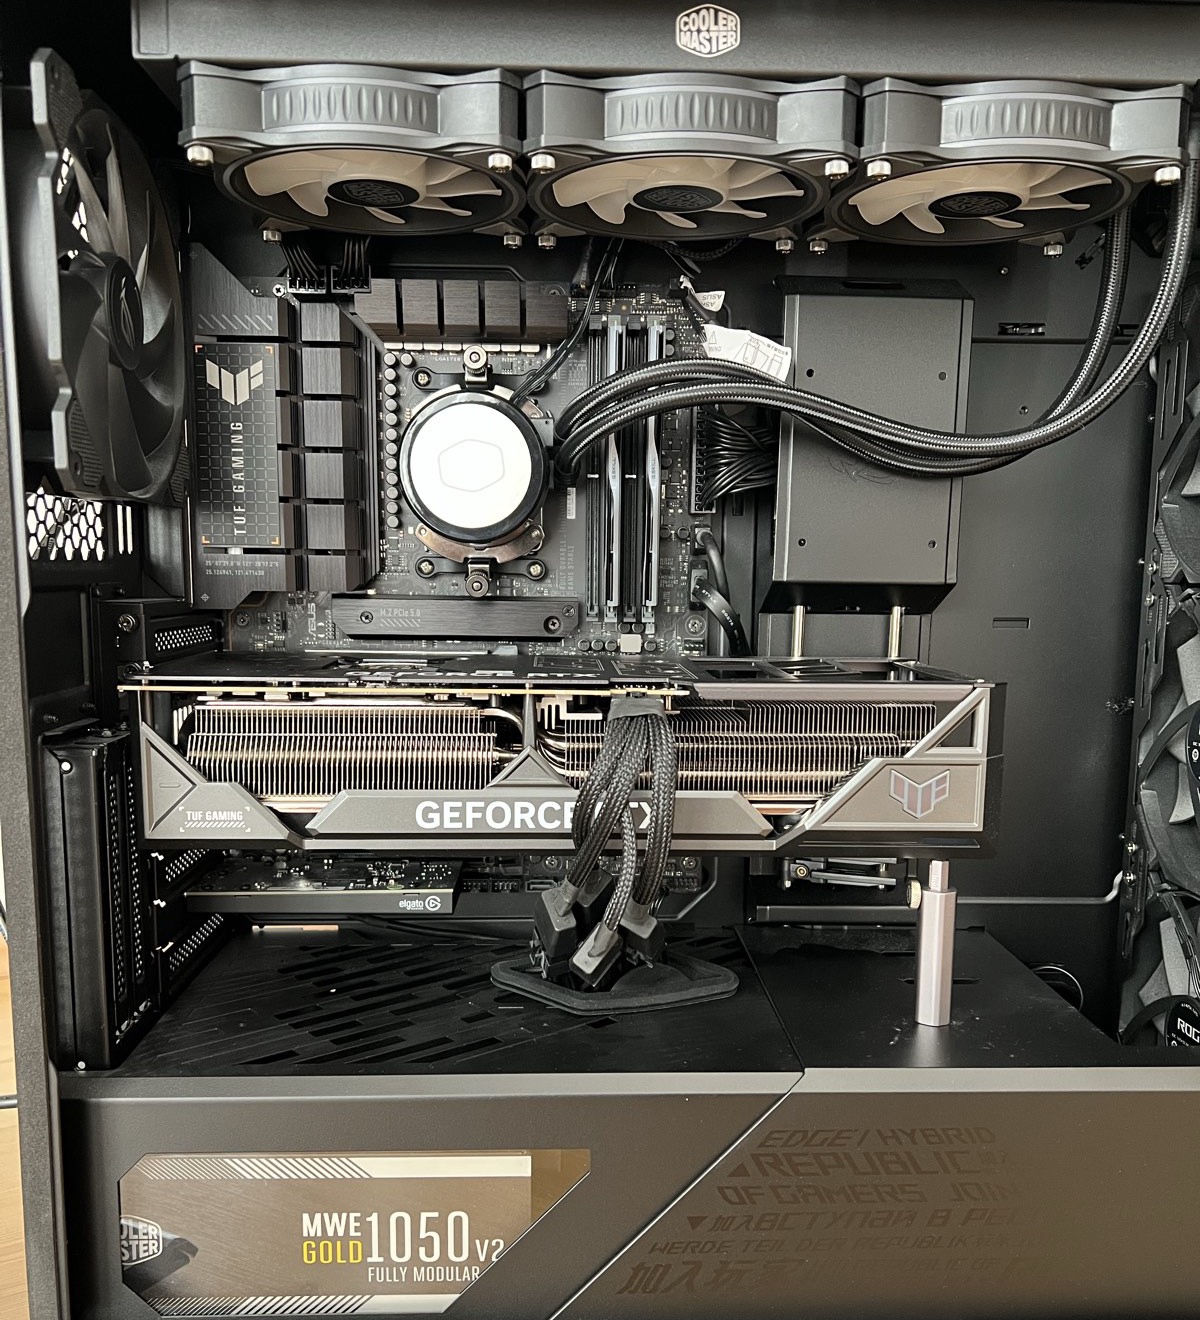
The model is Qwen2.5-7B-Instruct, served with vLLM on the RTX 4090. To measure it I wrote a small benchmark script. It sends a request, waits for the answer, and records how long each part takes. The prompts are 200 to 250 tokens and every answer is fixed at 150 tokens, so the runs are comparable.
One user
With one request at a time, the model produces 63 tokens per second. That is one token every 15.9 ms. A full 150-token answer takes 2.4 seconds.
Why 63
That number follows from the hardware. To produce one token, the GPU reads every weight in the model once. The weights are about 15.2 GB, and the 4090 reads memory at roughly 1 TB/s. 15.2 GB divided by 1 TB/s is 15.2 ms. The measured 15.9 ms is within 5% of that.
The arithmetic for one token takes a fraction of a millisecond on this card. The rest of the 15.9 ms is the GPU waiting for weights to arrive from memory. So for a single user, speed is set by memory bandwidth, not by how fast the GPU can do arithmetic.
This gives a rule you can use on any card: tokens per second is about memory bandwidth divided by the size of the weights.
The first word comes faster
The first word arrives after 0.03 seconds, less than the time for two tokens of the answer.
Before it writes, the model reads the prompt. It processes all the prompt tokens in one pass, so the weights are read once for 200 tokens instead of once per token. That step is limited by arithmetic, not by memory.
What fits on the card
The weights are not the only thing in VRAM. For every token the model has seen, it keeps intermediate results so it does not compute them again for the next word. That store is the KV cache, and it is what lets a model hold a conversation.
For this model the cost per token is easy to work out from its shape: 2 values, times 28 layers, times 4 key-value heads, times 128 numbers per head, times 2 bytes. That is 57,344 bytes, about 57 KB for every token of context. vLLM's own log reports the same figure.
A full 8,192-token conversation takes about 470 MB. After the weights and some working memory, about 5 GB of the card is left for the cache, which holds 94,336 tokens. One user with one conversation uses a small part of it.
The same model at 4 bits
Next I swapped in the same model with its weights stored in 4 bits instead of 16, using AWQ, and ran the same test. I also checked accuracy on 200 grade school math problems from GSM8K, with the same settings for both versions.
| 16-bit | 4-bit | |
|---|---|---|
| Weights in VRAM | 15.2 GB | 5.7 GB |
| Tokens per second | 63 | 162 |
| Time per token | 15.9 ms | 6.0 ms |
| Full answer | 2.4 s | 0.9 s |
| Wait for first word | 0.03 s | 0.03 s |
| Math problems right, of 200 | 177 | 177 |
If speed comes from reading the weights, a quarter of the bits should take a quarter of the time. But the 4-bit version is 37% of the size, not 25%. AWQ keeps the final layer at 16 bits and stores a small scale value for every group of 128 weights. With the real size, the same rule works: 15.9 ms times 0.37 is 5.9 ms. The measured value is 6.0 ms.
The first word did not get faster. Reading the prompt is limited by arithmetic, and 4-bit weights do not make the arithmetic smaller.
On accuracy, both versions solved 177 of the 200 problems. That does not make them the same model. Only 2 of the 200 answers were word for word identical, and each version missed seven problems that the other one got right. A 200-problem set can only resolve differences of about three points, and a 7B model usually loses one to three points at 4 bits. So the loss is real, but it is smaller than this test can see. A finer test, such as perplexity on long text, would show it.
After these runs the 4-bit version became the one I serve. I wanted a speech model and an embedding model on the same card, and the 9 GB that 4-bit freed made room for them.