Two Models Across Two DGX Sparks
Qwen3.8-Flash-Next and GLM-5.3-Flash split across both Sparks with TP=2: speed, memory, and a pelican from each.
In the last post Qwen3.8-Flash-Next ran on one Spark. In October NVIDIA published FP4-Local versions of two models: Qwen3.8-Flash-Next and GLM-5.3-Flash. FP4-Local is a 4-bit build for local hardware. The experts are stored in NVFP4, and NVIDIA trained the quantized model further to match the original (quantization-aware distillation). For Qwen it is 95 GiB, against 124 GiB for the NVFP4 version in the last post. I ran both with TP=2, which I described in the Sparks post. Each Spark holds half of every layer, and the two exchange results over the QSFP cable.
Both run on the same vLLM build, from a community image with faster kernels for this chip. Both have a small draft head (MTP) that guesses the next tokens, and the main model checks the guesses.
| Qwen3.8-Flash-Next | GLM-5.3-Flash | |
|---|---|---|
| Parameters | 125B, 6B active | 320B, 18B active |
| Weights | 95 GiB | 165 GiB |
| Start time | 9.5 min | 7.7 min |
| Free memory per Spark | 68 to 70 GiB | 20 to 21 GiB |
| KV cache | 306k tokens | 302k tokens |
Qwen also has the 51B lookup table from the last post. The free memory is while the server runs.
Random text
The first test is the same as in the earlier posts: one user, prompts of about 200 tokens of random filler, 150 tokens out, thinking off. GLM has no mode without thinking, so on this test it was writing its reasoning, not an answer.
| Qwen3.8-Flash-Next | GLM-5.3-Flash | |
|---|---|---|
| Tokens per second | 31.3 | 31.2 |
| 8k-token prompt, first token | 3.0 s | 3.6 s |
So the two numbers measure different text. The real prompts below compare the models better. On one Spark the same Qwen weights give 22 tokens per second here, so the second Spark adds about 40%.
Real prompts
Random filler cannot be guessed, so Qwen's draft head almost never helps on the test above. For Qwen I also ran six real prompts, five times each, at temperature 0.7. These are the medians:
| Prompt | Two Sparks | One Spark | Tokens per step, two Sparks |
|---|---|---|---|
| Write JSON | 94.1 | 62.4 | 4.33 |
| Write code | 89.7 | 58.0 | 4.04 |
| Rewrite a paragraph | 71.0 | 44.2 | 3.74 |
| Explain a concept | 68.1 | 46.5 | 3.29 |
| Translate to Turkish | 55.7 | 35.4 | 2.87 |
| Write a story | 50.6 | 33.6 | 2.25 |
Two Sparks are about 1.5 times faster on every prompt. The draft keeps the same number of tokens per step on one or two Sparks. What changes is the step: about 45 ms on two Sparks, about 71 ms on one.
I ran the same set on GLM at low, its lowest reasoning level. Both on two Sparks:
| Prompt | Qwen3.8-Flash-Next | GLM-5.3-Flash | Tokens per step, GLM |
|---|---|---|---|
| Write JSON | 94.1 | 50.3 | 4.40 |
| Write code | 89.7 | 41.0 | 3.83 |
| Rewrite a paragraph | 71.0 | 40.7 | 3.48 |
| Explain a concept | 68.1 | 33.3 | 3.08 |
| Translate to Turkish | 55.7 | 25.8 | 2.42 |
| Write a story | 50.6 | 24.6 | 2.20 |
Qwen is about twice as fast. GLM's draft keeps nearly as many tokens per step as Qwen's: 4.40 against 4.33 on JSON, 2.20 against 2.25 on the story. What differs is the step: about 90 ms on GLM, about 45 ms on Qwen. GLM has 18B active parameters per token, Qwen 6B.
A pelican from each
Simon Willison asks every new model for the same thing: "Generate an SVG of a pelican riding a bicycle". I asked both models at each of their reasoning levels, one sample per level.
Qwen3.8-Flash-Next
| low | medium | xhigh |
|---|---|---|
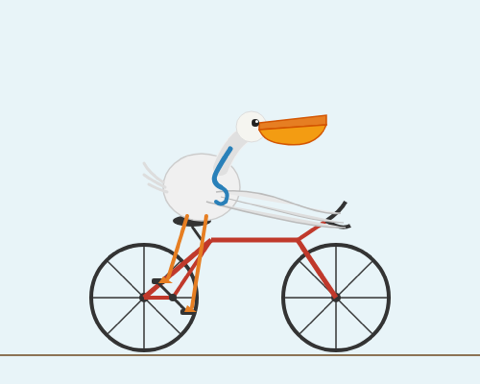 | 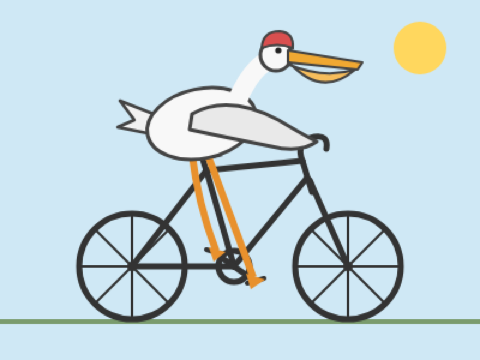 | 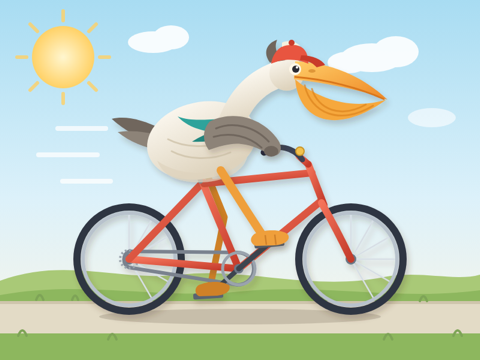 |
| 31 s | 39 s | 218 s |
GLM-5.3-Flash
| low | high | max |
|---|---|---|
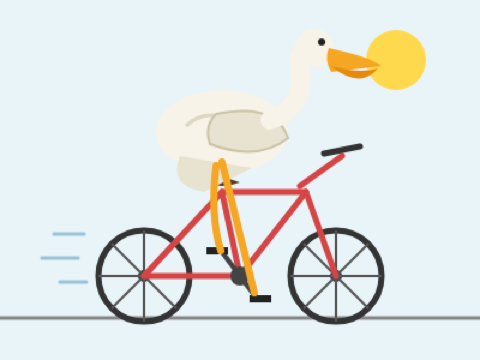 | 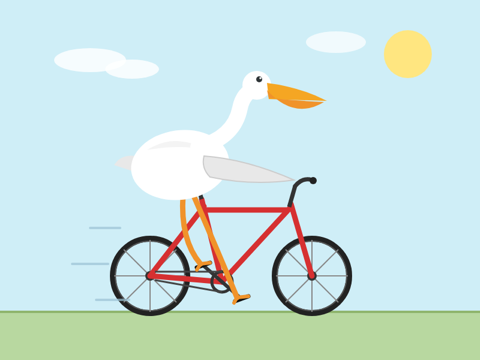 | 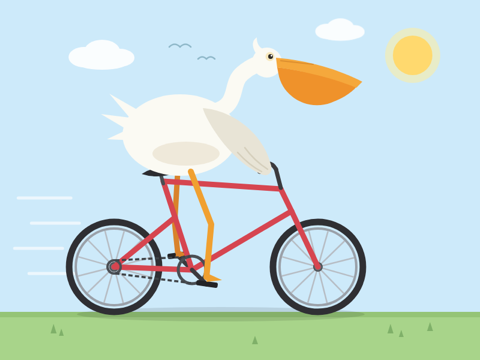 |
| 35 s | 77 s | 849 s |
GLM's high answer is close to its max answer, at a tenth of the time. Qwen's xhigh answer is clearly the best of its three, but it takes more than five times as long as medium.
| Level | Qwen3.8-Flash-Next | GLM-5.3-Flash |
|---|---|---|
| low | 31 s, 2,733 tokens | 35 s, 1,492 tokens |
| medium / high | 39 s, 3,133 tokens | 77 s, 3,012 tokens |
| highest | 218 s, 16,049 tokens | 849 s, 28,414 tokens |
| Tokens per second | 74 to 89 | 33 to 43 |
GLM has only low, high and max, so its middle row is "high".
On the pelican prompt Qwen is about twice as fast, the same gap as on the real prompts.
Both setups are in my recipes repo, with the commands I ran.